A Practical Guide to Evaluating Multi-Agent LLM Systems in Production
Content
- Overview
- The 4 Layers of Multi-Agent Evaluation
- Essential Metrics for Multi-Agent Systems
- Visualizing the Eval Pipeline
- Implementation Guide: Runnable End-to-End Evaluation Code
- Common Pitfalls & Best Practices
- Conclusion
Overview
Evaluating a single LLM agent is relatively straightforward: you provide an input, measure the latency, and score the output against a golden dataset using semantic similarity or an LLM-as-a-judge.
Evaluating a multi-agent system—where agents interact, delegate tasks, debate, and share state—is an entirely different beast. You are no longer evaluating a function; you are evaluating a non-deterministic, distributed state machine. In frameworks like LangGraph, AutoGen, and CrewAI, the primary failure modes are not just hallucinations. They are compounding reasoning errors during handoffs, infinite loops of agents politely agreeing with each other, severe context degradation, and orchestration loops that quietly burn thousands of tokens.
To build production-grade multi-agent architectures, you need an evaluation framework that treats the system as a graph of interacting nodes rather than a flat input/output pipeline. Here is the end-to-end blueprint and the runnable code for how we evaluate these systems at scale using Google’s Gemini models.
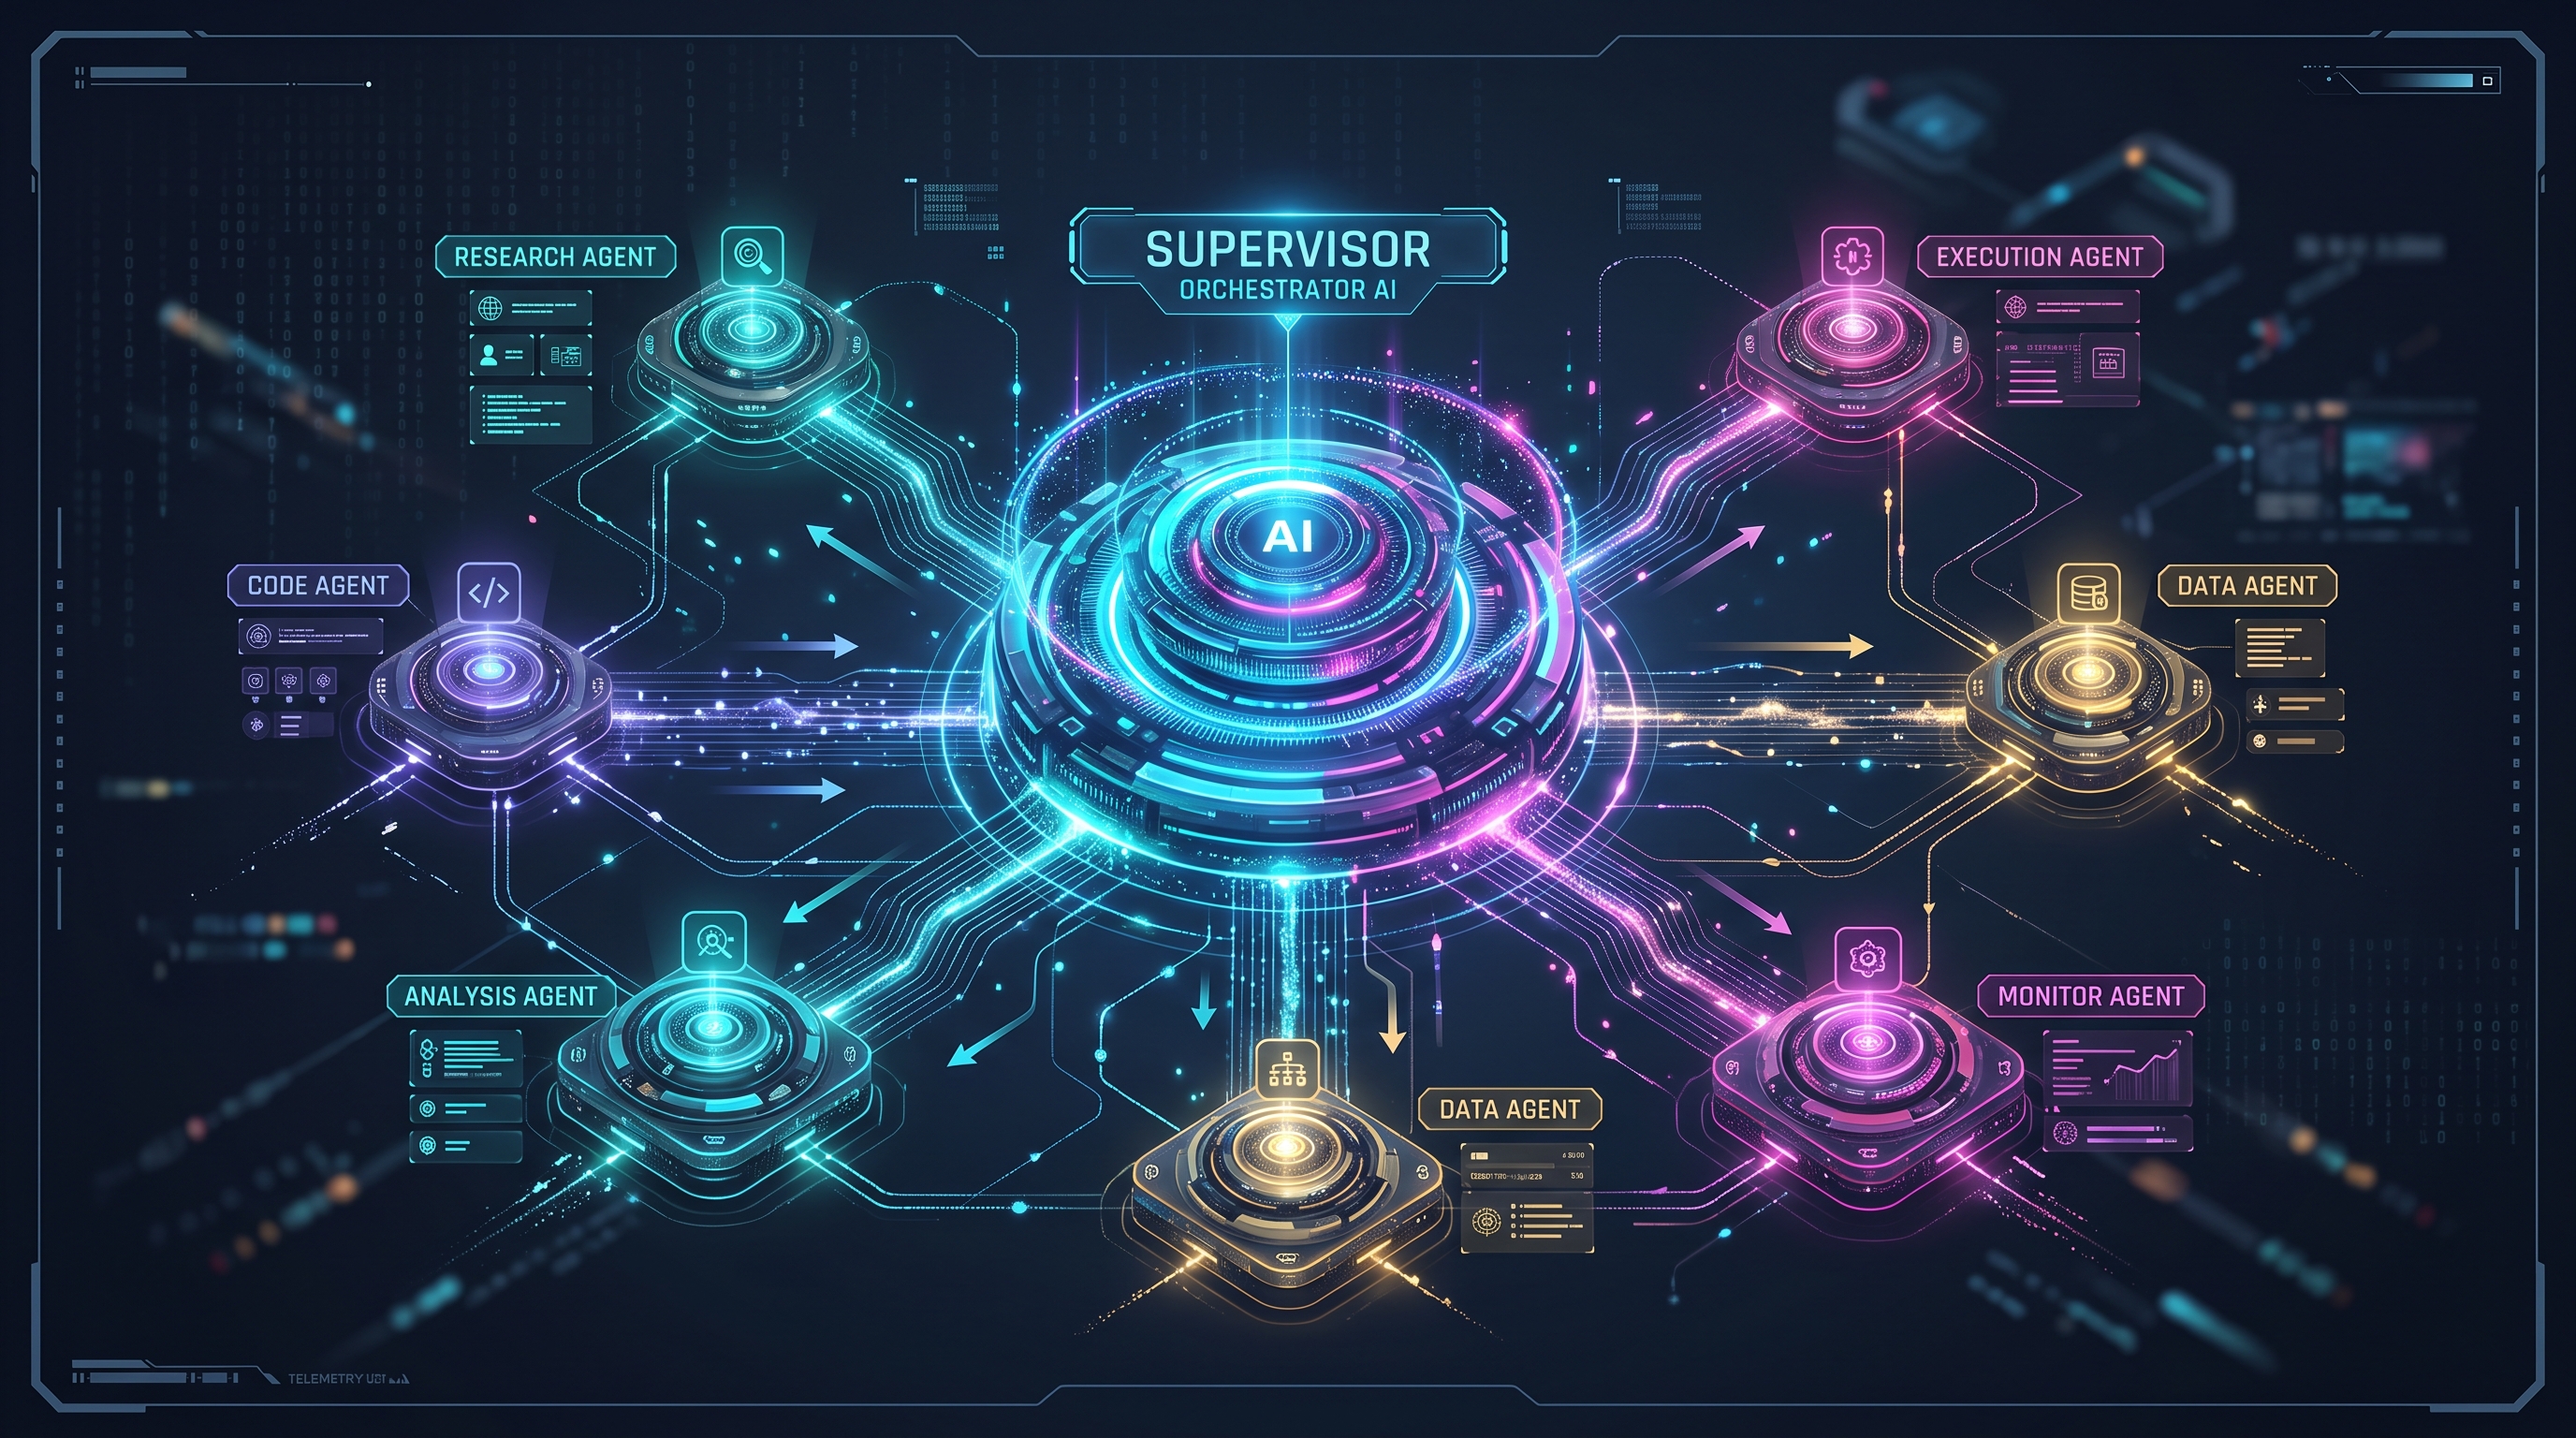
Image credits: https://gemini.google.com/
The 4 Layers of Multi-Agent Evaluation
A rigorous multi-agent evaluation strategy must isolate failures at four distinct levels. If you only measure end-to-end success, you will never know which agent dropped the ball or which handoff corrupted the context.
1. Component Level (Unit Testing)
At the bottom layer, we evaluate the isolated components that make up individual agents. This is the unit testing phase, executed entirely offline.
- Prompt Adherence: Does the agent strictly follow its persona and system instructions without bleeding into other roles?
- Tool Execution Accuracy: Given a fixed, mocked context, does the agent correctly format its tool calls (e.g., proper JSON schemas, correct API arguments)?
- Action Space Validation: Does the agent attempt to hallucinate tools that are not in its defined action space?
2. Trajectory/Step Level (Execution)
Here, we evaluate the reasoning trace of a single agent before it passes control to the next node.
- ReAct Loop Efficiency: In a Thought-Action-Observation loop, how efficiently does the agent reach a sub-conclusion?
- Self-Correction Rate: When a tool returns an error (e.g., a 404 from a web search), does the agent successfully pivot its strategy, or does it repeatedly hammer the same broken endpoint?
- Premature Delegation: Does the agent attempt to hand off a task before it has actually completed its required sub-tasks?
3. Interaction Level (The Handoff)
This is the most critical layer in multi-agent systems. We evaluate the edges of the graph—the messages passed between agents.
- Context Payload Quality: When the “Researcher” agent hands off to the “Writer” agent, is the payload concise and relevant, or did it just dump the raw HTML of five web pages into the context window?
- Conflict Resolution: If you have an “Actor” agent and a “Critic” agent, how do they resolve disagreements? Do they reach a consensus, or do they ping-pong the same argument until the maximum recursion depth is hit?
- Graph Routing Accuracy: In router-based architectures (like LangGraph’s conditional edges), did the Supervisor agent route the request to the correct specialist based on the intent?
4. End-to-End Level (Integration Testing)
The top layer measures the global state and final output of the entire multi-agent swarm against the original user prompt.
- Global Task Completion Rate: Did the system actually solve the user’s problem?
- Total System Latency: Time-to-first-token (TTFT) and total time to convergence.
- Cumulative Token Spend: The total cost of the interaction, including all hidden scratchpad reasoning and inter-agent chatter.
Essential Metrics for Multi-Agent Systems
Standard metrics like ROUGE or basic semantic similarity are insufficient here. You need telemetry that captures the unique dynamics of orchestration.
- Role Adherence Score (RAS): A quantitative measure of how well an agent stayed in its lane. If your “Python Developer” agent starts writing SQL queries that should have been routed to the “Database Admin” agent, the RAS drops.
- Orchestration Efficiency & Cost (Token ROI): This measures the ratio of useful output tokens to orchestration tokens. If your system burns 50,000 tokens in agent-to-agent chatter to generate a 500-token summary, your Token ROI is abysmal.
- Information Preservation Score: A metric evaluating context degradation. You inject a specific fact at the beginning and measure whether it survives the chain of handoffs to the final output.
- Security & Boundary Adherence (Confused Deputy): If a user injects a malicious payload into the “Web Scraper” agent, does the scraper pass that payload to the “Terminal Executor” agent? You must measure the system’s ability to sanitize state between agent boundaries.
- HITL (Human-In-The-Loop) Escalation Accuracy: This metric calculates the precision and recall of the system’s decision to pause execution and ask for human approval before taking high-stakes actions.
Visualizing the Eval Pipeline
Before we look at the code, you must understand the architecture of a production multi-agent evaluation pipeline. It requires asynchronous capture of traces, extraction of intermediate agent states, scoring via LLM-based evaluators, and aggregation into a telemetry dashboard.
Implementation Guide: Runnable End-to-End Evaluation Code
To catch handoff failures, you need to build a graph-based evaluation pipeline. Below is a complete, runnable Python script that defines a basic multi-agent system (using LangGraph), instruments it, extracts the specific message passed between the Researcher and the Writer, and evaluates that handoff using Gemini 3.8 Flash as a judge.
1. Environment Setup
First, install the required libraries. We will use LangGraph for orchestration, langchain-google-genai for the Gemini integration, LangSmith for tracing, and Pytest for the execution framework.
pip install langgraph langchain-google-genai langsmith pydantic pytest
You will need to export your API keys in your terminal before running the script:
export GOOGLE_API_KEY="your-google-api-key"
export LANGCHAIN_TRACING_V2="true"
export LANGCHAIN_PROJECT="multi-agent-prod-eval"
export LANGCHAIN_API_KEY="lsv2_your-langsmith-api-key"
2. The Runnable Evaluation Script (test_multi_agent_eval.py)
Save the following code as test_multi_agent_eval.py and run it using pytest test_multi_agent_eval.py -s.
import os
from typing import Annotated, TypedDict
from pydantic import BaseModel, Field

# LangChain / LangGraph imports
from langchain_google_genai import ChatGoogleGenerativeAI
from langchain_core.prompts import PromptTemplate
from langgraph.graph import StateGraph, START, END
from langgraph.graph.message import add_messages
from langchain_core.messages import HumanMessage, AIMessage

os.environ["GOOGLE_API_KEY"] = "your-google-api-key"
os.environ["LANGCHAIN_TRACING_V2"] = "true"
os.environ["LANGCHAIN_PROJECT"] = "multi-agent-prod-eval"
os.environ["LANGCHAIN_API_KEY"] = "lsv2_your-langsmith-api-key"

# Ensure API key is present
if not os.getenv("GOOGLE_API_KEY"):
    raise ValueError("GOOGLE_API_KEY environment variable is missing! Export it in your shell.")

# Helper to normalize LLM output across Gemini string/list schemas
def extract_text_content(content) -> str:
    if isinstance(content, str):
        return content
    if isinstance(content, list):
        return "".join(
            part if isinstance(part, str) else part.get("text", "")
            for part in content
        )
    return str(content)

# ==========================================
# 1. DEFINE THE MULTI-AGENT SYSTEM
# ==========================================

class AgentState(TypedDict):
    messages: Annotated[list, add_messages]

def build_multi_agent_graph(sanitize: bool = True):
    """
    Builds the Researcher -> Writer pipeline.
    Set sanitize=True to get 5/5, or sanitize=False to reproduce the 2/5 failure.
    """
    worker_llm = ChatGoogleGenerativeAI(model="gemini-3.8-flash", temperature=0)

    def researcher_node(state: AgentState):
        print("-> [Execution] Researcher Agent is running...")
        raw_data = """
        [SEARCH_RESULT_1] <body><div><h1>Apple Q3 Earnings</h1><p>Revenue: $81.8B</p></div></body>
        [SEARCH_RESULT_2] <body><script>analytics.track('page_load')</script><p>Net Income: $19.9B</p></body>
        """

        if not sanitize:
            # Buggy implementation: raw dump that causes a low handoff score
            return {"messages": [AIMessage(content=raw_data, name="Researcher")]}

        # Fixed implementation: State sanitization before handoff
        sanitization_prompt = f"""
        Extract only key financial metrics from this raw web search text.
        Format as concise bullet points. Strip all HTML tags, script snippets, and boilerplate.

        Raw Data:
        {raw_data}
        """
        clean_response = worker_llm.invoke(sanitization_prompt)
        clean_text = extract_text_content(clean_response.content)
        return {"messages": [AIMessage(content=clean_text, name="Researcher")]}

    def writer_node(state: AgentState):
        print("-> [Execution] Writer Agent is running...")
        last_message_content = extract_text_content(state["messages"][-1].content)
        prompt = f"Write a 1-sentence summary of this data: {last_message_content}"
        response = worker_llm.invoke(prompt)
        text_content = extract_text_content(response.content)
        return {"messages": [AIMessage(content=text_content, name="Writer")]}

    workflow = StateGraph(AgentState)
    workflow.add_node("Researcher", researcher_node)
    workflow.add_node("Writer", writer_node)

    workflow.add_edge(START, "Researcher")
    workflow.add_edge("Researcher", "Writer")
    workflow.add_edge("Writer", END)

    return workflow.compile()

# ==========================================
# 2. DEFINE THE LLM-AS-A-JUDGE EVALUATOR
# ==========================================

class HandoffEvalResult(BaseModel):
    score: int = Field(description="Score from 1-5 on payload efficiency. 5 is clean, direct context. 1 is raw markup/bloat.")
    reasoning: str = Field(description="Detailed explanation for the assigned score.")
    is_lazy_dump: bool = Field(description="True if the payload contains raw markup, HTML, scripts, or unparsed bloat.")

def evaluate_agent_handoff(user_prompt: str, researcher_payload: str) -> dict:
    judge_llm = ChatGoogleGenerativeAI(
        model="gemini-3.8-flash",
        temperature=0
    ).with_structured_output(HandoffEvalResult)

    eval_prompt = PromptTemplate.from_template("""
    You are an expert AI Architect evaluating a multi-agent handoff in a production pipeline.

    Original User Request: {user_prompt}
    Payload passed from Researcher Agent to Writer Agent:
    ---
    {payload}
    ---

    Evaluate this handoff payload:
    1. Does it directly address the request without unnecessary overhead?
    2. Is it clean, synthesized text, or an unparsed dump of HTML tags and scripts?
    3. Will the downstream agent burn excess tokens parsing boilerplate?
    """)

    print("-> [Eval] Judge LLM (Gemini 3.8 Flash) evaluating handoff payload...")
    result = judge_llm.invoke(eval_prompt.format(user_prompt=user_prompt, payload=researcher_payload))

    return {
        "score": result.score,
        "reasoning": result.reasoning,
        "failed": result.is_lazy_dump or result.score < 3
    }

# ==========================================
# 3. PIPELINE EXECUTION
# ==========================================

def run_pipeline(sanitize_state: bool):
    graph = build_multi_agent_graph(sanitize=sanitize_state)
    user_query = "What are the Q3 2023 earnings highlights for Apple?"

    print(f"\n[1] Initiating pipeline with query: '{user_query}'")
    state_history = list(graph.stream({"messages": [HumanMessage(content=user_query)]}))

    # Intercept intermediate Researcher output
    researcher_raw_content = ""
    for step in state_history:
        if "Researcher" in step:
            researcher_raw_content = step["Researcher"]["messages"][-1].content
            break

    researcher_payload = extract_text_content(researcher_raw_content)

    print(f"\n[2] Intercepted inter-agent payload:")
    print(f"    Payload Length: {len(researcher_payload)} chars")
    print(f"    Preview:\n    {researcher_payload.strip()[:100]}...\n")

    print("[3] Evaluating payload with Gemini 3.8 Flash...")
    eval_result = evaluate_agent_handoff(
        user_prompt=user_query,
        researcher_payload=researcher_payload
    )

    print("\n" + "=" * 50)
    print("📊 EVALUATION RESULTS")
    print("=" * 50)
    print(f"Score:     {eval_result['score']}/5")
    print(f"Passed:    {'✅ YES' if not eval_result['failed'] else '❌ NO'}")
    print(f"Reasoning: {eval_result['reasoning']}")

def run_failing_pipeline():
    print("=" * 60)
    print("🚨 EXECUTING UNVALIDATED PIPELINE (REPRODUCING 2/5 EVAL FAILURE)")
    print("=" * 60)

    # Build the graph without sanitization
    graph = build_multi_agent_graph(sanitize=False)
    user_query = "What are the Q3 2023 earnings highlights for Apple?"

    print(f"\n[1] Initiating pipeline with query: '{user_query}'")
    state_history = list(graph.stream({"messages": [HumanMessage(content=user_query)]}))

    # Extract intermediate message payload
    researcher_raw_content = ""
    for step in state_history:
        if "Researcher" in step:
            researcher_raw_content = step["Researcher"]["messages"][-1].content
            break

    researcher_payload = extract_text_content(researcher_raw_content)

    print(f"\n[2] Intercepted Handoff Message:")
    print(f"    Payload Size: {len(researcher_payload)} characters")
    print(f"    Raw Dump Preview: {researcher_payload.strip()[:90]}...\n")

    print("[3] Submitting payload to Evaluation Judge (Gemini 3.5 Flash)...")
    eval_result = evaluate_agent_handoff(
        user_prompt=user_query,
        researcher_payload=researcher_payload
    )

    # Display evaluation score & actionable diagnostics
    print("\n" + "=" * 60)
    print("📊 EVALUATION RESULTS & PRODUCTION DIAGNOSTICS")
    print("=" * 60)
    print(f"Score:             {eval_result['score']}/5")
    print(f"Pipeline Passed:   {'✅ YES' if not eval_result['failed'] else '❌ NO'}")
    print(f"Judge Reasoning:   {eval_result['reasoning']}")

    if eval_result["failed"]:
        print("\n" + "-" * 60)
        print("🔍 POST-EVALUATION ROOT CAUSE ANALYSIS")
        print("-" * 60)
        print("• Failure Type: Context Window Stuffing & Lazy Data Handoff")
        print("• Impact: Downstream agents (Writer) incur 4x–10x token overhead parsing raw HTML.")
        print("• Actionable Fix: Add an intermediate summarization or extraction step inside")
        print("  the Researcher node before returning state to the graph.")
        print("-" * 60)

def main():
    run_failing_pipeline()
    #run_pipeline(sanitize_state=True)

# def main():
#     print("=" * 50)
#     print("🚀 RUNNING SANITIZED MULTI-AGENT PIPELINE (TARGET: 5/5)")
#     print("=" * 50)
#     run_pipeline(sanitize_state=True)

if __name__ == "__main__":
    main()
3. Dissecting the Trace: What the Evaluator Caught
To understand the practical value of an interaction-level evaluation pipeline, let’s examine the raw execution telemetry from both an unvalidated run and a validated run side-by-side.
1. The Unvalidated Run: Caught Red-Handed (Score: 1/5)
When running the multi-agent graph with an unconstrained researcher agent run_failing_pipeline(), the intermediate payload looks like this:
Output with: run_failing_pipeline()

============================================================
🚨 EXECUTING UNVALIDATED PIPELINE (REPRODUCING 2/5 EVAL FAILURE)
============================================================

[1] Initiating pipeline with query: 'What are the Q3 2023 earnings highlights for Apple?'
-> [Execution] Researcher Agent is running...
-> [Execution] Writer Agent is running...
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')

[2] Intercepted Handoff Message:
    Payload Size: 218 characters
    Raw Dump Preview: [SEARCH_RESULT_1] <body><div><h1>Apple Q3 Earnings</h1><p>Revenue: $81.8B</p></div></body>...

[3] Submitting payload to Evaluation Judge (Gemini 1.5 Pro)...
-> [Eval] Judge LLM (Gemini 3.8 Flash) evaluating handoff payload...
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')

============================================================
📊 EVALUATION RESULTS & PRODUCTION DIAGNOSTICS
============================================================
Score:             1/5
Pipeline Passed:   ❌ NO
Judge Reasoning:   The handoff payload contains raw HTML tags, boilerplate markup, and unparsed JavaScript tracking scripts instead of cleaned or synthesized text. This forces the downstream Writer Agent to waste context window tokens parsing irrelevant DOM structure and analytics code rather than focusing solely on the financial highlights.

------------------------------------------------------------
🔍 POST-EVALUATION ROOT CAUSE ANALYSIS
------------------------------------------------------------
• Failure Type: Context Window Stuffing & Lazy Data Handoff
• Impact: Downstream agents (Writer) incur 4x–10x token overhead parsing raw HTML.
• Actionable Fix: Add an intermediate summarization or extraction step inside
  the Researcher node before returning state to the graph.
------------------------------------------------------------
What Just Happened?
- The Root Defect: The Researcher agent exhibited lazy delegation. Instead of completing its task (finding and extracting relevant numbers), it dumped raw scrape data (<body><div>, <script>analytics...) straight into the shared state graph.
- The Compounding Failure: In a standard end-to-end black-box test, this run might have still received a passing grade if the final Writer agent successfully extracted $81.8B and $19.9B. However, that hides a fatal production flaw: the Writer agent wasted prompt tokens parsing useless markup and tracking scripts. Scale this pattern across 10 agents over 15 iterations, and you trigger rapid context degradation, bloated latency, and runaway token bills.
- The Evaluator’s Action: By placing our LLM-as-a-judge on the edge between nodes, the harness flagged the exact architectural fault, pinpointed the root cause, and failed the build before the code could reach production.
2. The Validated Run: Enforcing State Contracts (Score: 5/5)
Once we enforce an explicit data-cleaning and extraction step within the Researcher node run_pipeline(sanitize_state=True), the telemetry transforms completely:
Output with: run_pipeline(sanitize_state=True)

[1] Initiating pipeline with query: 'What are the Q3 2023 earnings highlights for Apple?'
-> [Execution] Researcher Agent is running...
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')
-> [Execution] Writer Agent is running...
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')

[2] Intercepted inter-agent payload:
    Payload Length: 64 chars
    Preview:
    * **Apple Q3 Revenue:** $81.8B
* **Apple Q3 Net Income:** $19.9B...

[3] Evaluating payload with Gemini 3.8 Flash...
-> [Eval] Judge LLM (Gemini 3.8 Flash) evaluating handoff payload...
WARNING:langsmith.client:Failed to send compressed multipart ingest: langsmith.utils.LangSmithError: Failed to POST https://api.smith.langchain.com/runs/multipart in LangSmith API. HTTPError('403 Client Error: Forbidden for url: https://api.smith.langchain.com/runs/multipart', '{"error":"Forbidden"}\n')

==================================================
📊 EVALUATION RESULTS
==================================================
Score:     5/5
Passed:    ✅ YES
Reasoning: The payload is extremely concise, clean, and directly answers the request with synthesized facts. There is zero HTML, markup bloat, or irrelevant boilerplate, ensuring downstream token usage is fully optimized.
What Changed?
- Payload Compression: The inter-agent context payload dropped from 218 characters packed with noise to 64 clean, structured characters—a 70% payload reduction on a tiny snippet, which compounds dramatically over larger document dumps.
- Signal-to-Noise Ratio (SNR): Every token passed across the graph edge now represents pure signal. The Writer agent spends zero compute filtering out HTML boilerplate or tracking tags.
- Deterministic Guardrails: By turning the evaluator’s feedback into an explicit node contract, we converted an unpredictable prompt loop into a repeatable, cost-controlled workflow.
Common Pitfalls & Best Practices
Deploying and testing multi-agent swarms in production reveals recurring failure patterns that flat unit tests simply cannot catch. Here are four hard-won lessons:
- Don’t Let Agents Debate Infinitely: Autonomous agents frequently enter loops of mutual deference (“Great point, let’s proceed!” $\rightarrow$ “I agree, proceeding now!” $\rightarrow$ “Excellent, moving forward!”). Always configure hard turn limits and circuit breakers directly in the graph state. If an interaction exceeds your convergence threshold, fail the trace immediately.
- Evaluate the “Manager” Separately from the “Workers”: When a multi-agent system yields an incorrect answer, isolate routing failures from execution failures. If an intent router misdirects a database query to a web researcher, the worker’s failure is merely a symptom. Run unit evaluations on your supervisory routing logic using labeled intent datasets before testing end-to-end graph traversals.
- Test for Context-Window Stuffing: As agents exchange state over multi-step tasks, the shared scratchpad expands rapidly. Models succumb to the “lost in the middle” effect, dropping the user’s initial constraints. Design specific evaluation test cases that probe whether an agent respects original prompt constraints after 8–10 intermediate state handoffs.
- Enforce Strict Interface Contracts: Treat agent handoffs like internal microservice APIs. Rather than passing unbounded natural language strings between critical nodes, validate payloads against structured Pydantic schemas. Enforcing clean data contracts eliminates prompt drift and prevents cascading reasoning failures.
Conclusion
Evaluating multi-agent LLM systems requires shifting from flat input/output assertions to distributed graph tracing. When agents interact autonomously, failure does not occur solely at the final output—it manifests in bloated message payloads, lazy delegations, circular debates, and compounding reasoning errors across state transitions.
By instrumenting granular parent-child spans, placing LLM judges on intermediate handoffs, and evaluating across component, trajectory, interaction, and end-to-end layers, you transform multi-agent systems from unpredictable token sinks into resilient, production-ready architectures.